PC Slower Than It Used to Be?
Recommended Free Tools
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.
Run a Free PC Scan →Free scan · Windows 10 & 11
ThatPainter is reader-supported. When you buy through links on our site, we may earn an affiliate commission. Learn More
DreamBooth can personalize a pretrained Stable Diffusion model so a unique token represents your appearance in portraits, illustrations, fashion images, and other scenes. You are not training an AI model from scratch: you are fine-tuning an existing checkpoint or training a smaller adapter.
For most individual users, start with DreamBooth LoRA. It creates a smaller, easier-to-load file than full DreamBooth training while leaving the base model separate. You will need a compatible model, a varied set of face photos, and access to a suitable NVIDIA GPU locally or in the cloud.
#1 Best Overall
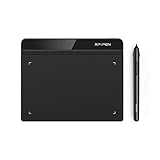
- Battery-Free Pen: StarG640 drawing tablet is the perfect replacement for a traditional mouse! The XPPen advanced Battery-free PN01 stylus does not require charging, allowing for constant uninterrupted Draw and Play, making lines flow quicker and smoother, enhancing overall performance
- Ideal for Online Education: XPPen G640 graphics tablet is designed for digital drawing, painting, sketching, E-signatures, online teaching, remote work, photo editing, it's compatible with Microsoft Office apps like Word, PowerPoint, OneNote, Zoom, Xsplit etc. Works perfect than a mouse, visually present your handwritten notes, signatures precisely
- Compact and Portable: The G640 art tablet is only 2 mm thick, it's as slim as all primary level graphic tablets, allowing you to carry it with you on the go
- Chromebook Supported: XPPen G640 digital drawing tablet is ready to work seamlessly with Chromebook devices now, so you can create information-rich content and collaborate with teachers and classmates on Google Jamboard’s whiteboard; Take notes quickly and conveniently with Google Keep, and effortlessly sketch diagrams with the Google Canvas
- Multipurpose Use: Designed for playing OSU! Game, digital drawing, painting, sketch, sign documents digitally, this writing tablet also compatible with Microsoft Office programs like Word, PowerPoint, OneNote and more. Create mind-maps, draw diagrams or take notes as replacement for mouse
What DreamBooth does
The original DreamBooth technique associates a rare identifier with a particular subject by fine-tuning a pretrained text-to-image diffusion model on a small image set. In practice, you might use the token zxy-person and then prompt:
a cinematic portrait of zxy-person in a rain-soaked cityThe model learns a statistical visual representation associated with that token. It does not understand your identity like a person does, and it cannot guarantee an exact likeness in every pose or style. Results depend on the base model, photos, captions, resolution, learning rate, training duration, and inference tool.
The original paper demonstrated personalization from only a few images, and the official Diffusers example describes roughly three to five subject images. That is a technical starting point, not a promise of good face likeness. For a practical face dataset, I recommend starting with 10–20 varied images rather than a handful of nearly identical selfies. See the original DreamBooth paper and the official Diffusers example.
DreamBooth, DreamBooth LoRA, and alternatives
| Goal | Best starting point |
|---|---|
| Fast experimentation | Reference-image workflow or hosted trainer |
| Small downloadable personalization file | DreamBooth LoRA |
| Maximum control and a dedicated checkpoint | Full DreamBooth |
| Learning a visual concept or style | LoRA or textual inversion |
| Privacy-sensitive face training | Local training |
| No suitable local GPU | Cloud GPU with an official training script |
Full DreamBooth
Full DreamBooth updates substantial portions of the model and can produce a dedicated personalized checkpoint. It may retain identity strongly, but the output is larger, training is more demanding, and excessive training can damage the model’s general ability to generate ordinary people, scenes, and styles.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →DreamBooth LoRA
A LoRA trains a smaller adapter that is loaded alongside the compatible base model. It is easier to store, test at different strengths, and keep private. It is not universally better: identity retention varies by model family and prompt, and a LoRA must be paired with the correct base model.
Other methods
- Textual inversion learns an embedding rather than broadly adapting the model. It is compact but can be less flexible for identity.
- Reference-image and IP-Adapter workflows use a photo during generation instead of training a personalized model.
- Online avatar services are simpler but require sending biometric images to a third party.
Do not call every face-personalization workflow “DreamBooth.” The method determines what is trained, what file is produced, and how it must be loaded later.
What you need
- A compatible Stable Diffusion checkpoint. SD 1.x, SDXL, and newer model families use different scripts, resolutions, and resource requirements.
- About 10–20 varied images of the subject as a practical starting recommendation.
- A recent isolated Python environment using
venvor Conda. - An NVIDIA GPU with a working CUDA/PyTorch setup, or a cloud GPU.
- Disk space for the base model, cached dependencies, checkpoints, validation images, and output adapter.
- A Hugging Face account and any required model access approval. Some gated models require accepting terms before downloading.
GPU memory expectations
There is no universal VRAM requirement. Memory changes with model family, resolution, batch size, optimizer, precision, text-encoder training, and whether you train the full model or a LoRA.
- A 16 GB GPU may be workable with gradient checkpointing and the 8-bit optimizer.
- A 12 GB GPU may additionally need memory-efficient attention and
--set_grads_to_none. - An 8 GB GPU may require CPU/NVMe offloading and can be slow or difficult.
- Full DreamBooth, SDXL, higher resolution, and text-encoder training generally require more memory than a basic LoRA run.
These are guidance ranges, not guarantees. The current Diffusers DreamBooth guide documents the relevant memory-saving combinations.
Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchPC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Prepare a face dataset
Create a private directory containing images of one subject. Use front, three-quarter, and side views; neutral and lightly varied expressions; head-and-shoulders and some upper-body crops; indoor and outdoor lighting; and several backgrounds.
Rank #2
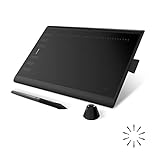
- Working Area Configuration - HUION art tablet equips with a 10 x 6.25 inches working area, providing the user with the most comfortable size to work; the 10mm slim structure and minimalist design of appearance make the drawing tablet more attractive.
- Tilt Function Battery-free Stylus: This computer graphics tablet come with a battery-free stylus PW100, no need to charge, allowing for constant uninterrupted drawing. ±60° tilt support enables imitation of lines input with diverse drawing gestures, with accuracy ensured.
- Press Keys:12 programmable press keys plus 16 programmable soft keys, you can set shortcut keys on drawing tablet's driver based on your preferences, such as erase, zoom in/out, scroll up and down, and so on.
- Compatibility: HUION graphics tablet supports Windows 7 or later/ macOS 10.12 or later/ Android 6.0 or later/ Linux (Ubuntu). A USB adapter is required to connect to a Mac computer. H1060P supports various mainstream design and drawing software, including PS, SAI, AI, CDR, etc. (Please note: The H1060P is compatible with Ubuntu, but it requires the use of the Xorg display server. Wayland is not supported.)
- NOTE: You can easily connect your phone to the art tablet via the OTG connector; while iPhone and iPad are NOT at the moment. The cursor will not show up in the SAMSUNG Galaxy S series at present. If you are not sure whether the product is compatible with your Phone or any help, please contact us.
Exclude sunglasses, masks, heavy filters, extreme makeup, burst-mode duplicates, and photos where another person appears unless that person is intentionally part of the concept and has consented. Keep identity consistent without making every photograph identical.
A repetitive set of selfies can make the model memorize the photos instead of learning a representation that generalizes to new clothing, backgrounds, angles, and artistic styles. Avoid letting one hairstyle, pair of glasses, outfit, or lighting setup become inseparable from the identity.
A simple layout is:
project/
  instance-images/
    face-01.jpg
    face-02.jpg
    face-03.jpg
  validation/
  output/
Choose a unique token
Use a rare token that does not already have a strong meaning in the model. Avoid a common first name or ordinary word. For example:
Free tools Windows power users keep installed
One-click scans. No signup required.
Instance token: zxy-person
Instance prompt: a photo of zxy-person
Class prompt: a photo of a person
The instance prompt identifies the specific subject. The class prompt describes the broad category. Keep the token and instance prompt consistent throughout training and generation.
Prior preservation
Prior preservation is optional. It supplies generic class images—such as images of people—to help preserve the model’s broader understanding of the class while it learns the individual.
With prior preservation, you have extra setup and class images but may better preserve the general “person” concept. Without it, the workflow is simpler, but the model may narrow more aggressively around the training subject. Prior preservation does not automatically prevent overfitting; dataset quality and training settings still matter.
Install Diffusers and Accelerate
The reproducible baseline for this guide is the official Hugging Face Diffusers training code. The examples live in a changing source repository, so commands and flags can change. Check the current README and run --help before training.
Create and activate an isolated environment:
python -m venv dreambooth-envOn macOS or Linux:
source dreambooth-env/bin/activateOn Windows PowerShell:
.dreambooth-envScriptsActivate.ps1Install the current training examples:
git clone https://github.com/huggingface/diffusers
cd diffusers
pip install -e .
cd examples/dreambooth
pip install -r requirements.txt
Configure Accelerate:
accelerate configFor a noninteractive default configuration, use:
accelerate config defaultOptional low-memory support may require:
pip install bitsandbytesInspect the available arguments for the exact checkout you installed:
accelerate launch train_dreambooth.py --helpAs of the research check on August 18, 2026, the official setup recommended installing Diffusers from source and then installing the example-specific requirements. Record the exact Diffusers commit or release, base model identifier, operating system, and GPU if you need reproducible results.
Rank #3
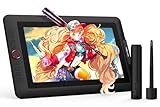
- PLEASE NOTE:XPPen Artist13.3 Pro drawing tablet Need to connect with computer,you need to use it with your computer or laptop, the 3 in 1 cable is included
- Drawing Tablet with Screen: Tilt Function- XPPen Artist 13.3 Pro supports up to 60 degrees of tilt function, so now you don't need to adjust the brush direction in the software again and again. Simply tilt to add shading to your creation and enjoy smoother and more natural transitions between lines and strokes
- Graphics Tablets: High Color Gamut- The 13.3 inch fully-laminated FHD Display pairs a superb color accuracy of 88% NTSC (Adobe RGB≧91%,sRGB≧123%) with a 178-degree viewing angle and delivers rich colors, vivid images, and dazzling details in a wider view. Your creative world is now as powerful as it is colorful
- Drawing Pad: One is enough- The sleek Red Dial on the display is expertly designed with creators in mind, its strategic placement allows for natural drawing postures. With just one wheel, you can effortlessly zoom in and out, adjust brush sizes, and flip the canvas—all tailored to suit the habits of everyday artists. The 8 customizable shortcut keys allow you to personalize your setup, streamlining your workflow and enhancing creative efficiency
- Universal Compatibility & Software Support:supports Windows 7 (or later), Mac OS X 10.10 (or later), Chrome OS 88 (or later), and Linux systems. Fully compatible with major creative software including Photoshop, Illustrator, SAI, and Blender 3D. Register your device to access additional programs like ArtRage 5 and openCanvas for expanded creative possibilities.
Train full DreamBooth
The following is a template, not a guaranteed copy-and-paste command. It assumes a compatible 512-pixel model and the full-training script. Use the model’s documented resolution and confirm every flag with the installed script.
export MODEL_NAME="YOUR_COMPATIBLE_MODEL_ID"
export INSTANCE_DIR="path/to/your-face-images"
export OUTPUT_DIR="path/to/output"
export INSTANCE_PROMPT="a photo of zxy-person"

accelerate launch train_dreambooth.py
  --pretrained_model_name_or_path="$MODEL_NAME"
  --instance_data_dir="$INSTANCE_DIR"
  --output_dir="$OUTPUT_DIR"
  --instance_prompt="$INSTANCE_PROMPT"
  --resolution=512
  --train_batch_size=1
  --gradient_accumulation_steps=1
  --learning_rate=5e-6
  --lr_scheduler="constant"
  --lr_warmup_steps=0
  --max_train_steps=800
  --mixed_precision="fp16"
  --gradient_checkpointing
  --use_8bit_adam
The learning rate and 800-step limit are starting points, not universal optimums. The model identifier may require authentication or access approval. A different model family may require a different script, resolution, scheduler, or text-encoder configuration.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Important controls include:
--pretrained_model_name_or_path: the base checkpoint.--instance_data_dir: your private face-image directory.--instance_prompt: the prompt containing your unique token.--resolution: the training resolution supported by the base model.--train_batch_size: lower this to 1 when memory is limited.--max_train_steps: the total training duration; more is not automatically better.--mixed_precision,--gradient_checkpointing, and--use_8bit_adam: memory-saving options.
Enable validation prompts or save intermediate checkpoints where the selected script supports them. Inspect those images instead of waiting for the final output. Stop when identity and prompt flexibility are good; continuing until the loss is low can produce memorized training photographs.
Train a DreamBooth LoRA instead
For most beginners, LoRA is the better first experiment because the adapter is smaller and easier to keep separate from the base model. It also lets you test strength at inference time and avoids creating a large personalized checkpoint.
Use the script that matches your model family. For an SDXL base model, the current Diffusers examples include a model-specific SDXL DreamBooth-LoRA script. A generic structure is:
accelerate launch train_dreambooth_lora_sdxl.py
  --pretrained_model_name_or_path="YOUR_SDXL_MODEL_ID"
  --instance_data_dir="path/to/images"
  --output_dir="path/to/lora-output"
  --instance_prompt="a photo of zxy-person"
  --resolution=1024
  --train_batch_size=1
  --gradient_accumulation_steps=1
  --learning_rate=1e-4
  --max_train_steps=1000
  --mixed_precision="fp16"
These values are placeholders. Do not use this SDXL command with an SD 1.5 checkpoint, and do not assume every UI accepts every adapter format. Check the current Diffusers training overview and the script’s help output.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsSDXL and larger configurations can require substantially more memory. The Diffusers advanced training material references experiments using a single 40 GB A100 for certain configurations; that does not mean every SDXL LoRA run needs that GPU, but it illustrates why model family and settings matter.
Generate art with the trained result
At inference time, load the same compatible base model used during training. Then load either the full DreamBooth checkpoint or the LoRA adapter through a UI or library that supports that architecture.
Use your unique token in prompts, but vary the context so you can test generalization:
Rank #4

- Large Active Drawing Space: UGEE M708 V3 graphic drawing tablet features 10 x 6 inch large active drawing space with papery texture surface, provides enormous and smooth drawing for your digital artwork creation, offers no-lag sketch and painting experience
- 16384 Passive Stylus Technology: A more affordable passive stylus technology offers 16384 levels of pressure sensitivity allows you to draw accurate lines of any weight and opacity according to the pressure you apply to the pen, sharper line with light pressure and thick line with hard pressure for artistry design or unique brush effect for photo retouching
- Compatible with Multiple System and Softwares: Powerful compatibility, tablet for drawing computer, perform well with Windows 11/10/8/7, Mac OS X 10.10 or later, Android 10.0 or later, mac OS 10.12 or later, Chrome OS 88 or later and Linux; Driver program works with creative software such as Photoshop, Illustrator, Macromedia Flash, Comic Studio, SAI, Infinite Stratos, 3D MAX, Autodesk MAYA, Pixologic ZBrush and more
- Ergonomically Designed Shortcuts: 8 customizable express keys on the side for short cuts like eraser, zoom in and out, scrolling and undo, provide a lot more for convenience and helps to improve the productivity and efficiency when creating with the drawing tablet
- Easy Connectivity for Beginners: The UGEE M708 V3 offers USB to USB-C connectivity, plus adapters for USB C, ensuring easy connection to various devices and allowing beginner artists to set up quickly and focus on their creativity without compatibility concerns; Whether using a laptop, desktop, chromebook, or tablet, the UGEE M708 V3 provides a seamless experience for those just starting their digital art journey
a cinematic portrait of zxy-person in a rain-soaked cityzxy-person as a watercolor illustration, warm paper texturea studio headshot of zxy-person wearing a green jacketzxy-person hiking in a mountain landscape, editorial photographyFor a LoRA, adjust its strength carefully. Increasing strength may improve identity in one prompt while reducing image quality or making the result resemble the training photos too closely. Test several seeds and prompts rather than judging one image.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Do not assume that every .safetensors file is interchangeable. Confirm whether the output is a full checkpoint or LoRA, which model family it supports, whether a VAE or text encoder is required, and whether your target UI supports the architecture. A LoRA trained for one base model is not a universal face filter.
How to tell whether training worked
Evaluate validation images with prompts that differ from the training captions. A useful result should preserve recognizable facial structure while following new instructions for clothes, locations, lighting, camera angle, and style.
- Is the face recognizable from different angles?
- Are the eye and mouth structure, hairline, and face shape reasonably consistent?
- Can the model change clothing and background?
- Does it work in both photography and non-photographic styles?
- Does it generate new compositions rather than reproduce a training photo?
- Do hands, accessories, and backgrounds remain coherent?
A strong result generalizes beyond the exact poses and backgrounds in the dataset. Perfect photographic resemblance is not the only measure: a model that copies one selfie exactly may be less useful than one that produces varied, recognizable artwork.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Troubleshooting
Out-of-memory errors
Try these changes in order, checking the current script’s supported flags:
- Set the batch size to
1. - Enable mixed precision.
- Enable gradient checkpointing.
- Use the 8-bit optimizer.
- Enable xFormers memory-efficient attention where supported.
- Reduce resolution.
- Disable text-encoder training if the selected script permits it.
- Use CPU/NVMe offloading or a larger cloud GPU.
- Switch from full DreamBooth to LoRA.
The official guide documents different combinations for 16 GB, 12 GB, and 8 GB GPUs. An 8 GB configuration may run with offloading, but it is not a guarantee of practical success for every model.
The face resembles the photos but not the person in new scenes
Likely causes include too few images, nearly identical poses, excessive steps, a learning rate that is too high, prompts too close to the training captions, or low-quality filtered photos. Add varied identity-consistent images, reduce steps, lower the learning rate, and compare intermediate checkpoints.
The model produces generic people
Confirm that the unique token appears consistently in prompts, the instance directory is correct, the training did not end too early, and the exact base model is loaded at inference. For a LoRA, test a modest range of adapter strengths. A more distinctive token may help if the original token already carries meaning.
The face is distorted
Check low-resolution or poorly cropped images, extreme angles, excessive augmentation, overtraining, an incompatible VAE, and a model-family mismatch between training and inference. Include clean, well-lit images with enough facial detail.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →Best Value

- Word-first 16K Pressure Levels: The upgraded stylus features 16,384 levels of pressure sensitivity and supports up to 60 degrees of tilt, delivering smoother lines and shading for a natural drawing experience. With no battery or charging needed, it operates like a real pen, making it easy for beginners to create effortlessly. This functionality helps novice artists develop their skills and explore their creativity without the intimidation of complex tools
- Designed for Beginners: This drawing pad desinged with 8 customizable shortcuts for both right and left-hand users, express keys create a highly ergonomic and convenient work platform
- Perfectly Adapted for Android: The XPPen Deco 01 V3 art tablet supports connections with Android devices running version 10.0 and above. It is recommended to download the XPPen Tools Android application, which adapts to your smartphone's screen aspect ratio, ensuring accurate mapping. It also supports mapping on Android screens with different aspect ratios in portrait mode
- Large Drawing Space, Bigger Bold Inspiration: This expansive drawing pad has10 x 6.25-inch helps you break through the limit between shortcut keys and drawing area
- Easy Connectivity for Beginners: The Deco 01 V3 offers USB-C to USB-C connectivity, plus adapters for USB C. This ensures easy connection to various devices, allowing beginner artists to set up quickly and focus on their creativity without compatibility concerns. Whether using a laptop, tablet, or desktop, the Deco 01 V3 provides a seamless experience, making it an ideal choice for those just starting their digital art journey
Hair, age, skin tone, glasses, or clothing change unexpectedly
The dataset may have correlated an incidental attribute with identity. If every image has the same hairstyle, glasses, outfit, or lighting, the model may treat that feature as part of the subject. Add deliberate but reasonable variation while keeping the person clearly identifiable.
The model copies recognizable photographs
This is both a quality and privacy failure. A tiny repetitive dataset and too many steps can cause memorization. Stop using the affected checkpoint, reduce training, replace repetitive images, and keep the original photos and outputs private.
The file will not load in the target UI
Check the base model family, file format, full-checkpoint-versus-LoRA distinction, required VAE or text encoder, UI architecture support, and whether conversion is required. Reopen the model with the exact base checkpoint used for training.
Local versus cloud training
Train locally
Local training is the strongest privacy option and is convenient for repeated experiments if you already own a capable GPU. The trade-offs are CUDA, PyTorch, xFormers, and dependency troubleshooting, plus electricity and hardware limits.
Use a cloud GPU
Cloud training is useful for a one-off run, a larger model, or a computer without enough VRAM. It is not automatically private: you upload face images to infrastructure you do not control. Delete persistent volumes, checkpoints, temporary files, and public links when finished, and review access tokens and permissions.
RunPod offers configurable GPU environments for training and fine-tuning. Its published rates vary by GPU and cloud type; a pricing check on August 18, 2026 showed examples including approximately $0.50/hour for an RTX 3090 and $0.69/hour for an RTX 4090, but rates and availability change. See RunPod’s GPU page and current pricing.
Vast.ai is a marketplace, so hosts set prices and rates fluctuate. GPU compute, storage, and bandwidth are billed separately, and storage can continue charging while an instance is stopped but not deleted. Compare live offers using the Vast.ai marketplace and read its pricing and billing documentation.
Replicate is more API-oriented and bills model usage or training by hardware runtime. It may suit developers, but do not assume a particular endpoint is a turnkey DreamBooth face trainer without verifying the current model and training support. See Replicate pricing.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Scan for outdated or missing drivers - takes under a minute3Repair Windows errors before they cause bigger problemsEstimate compute cost as:
estimated compute cost = hourly GPU price × training hoursAlso account for storage, bandwidth, taxes, minimum charges, and interrupted or preemptible runs. Open-source software is not necessarily cost-free when you include hardware, electricity, storage, or rented compute.
Privacy, consent, and responsible use
- Train only on your own face or images for which you have explicit permission.
- Do not use the method to impersonate another person, create sexualized images of a real person without consent, or evade identity protections.
- Treat face photos, tokens, checkpoints, and embeddings as sensitive personal data.
- Keep datasets, cloud volumes, model files, and repository links private.
- Remove metadata and public access before sharing anything.
- Review the base model license and restrictions on commercial use.
- Label generated portraits when viewers could mistake them for documentary photography.
- Check the privacy, publicity, copyright, biometric-data, and platform rules that apply to your situation.
Personalized image models can be abused for synthetic media. Research such as Anti-DreamBooth has examined defenses against malicious personalized text-to-image synthesis. Technical ability does not grant permission to train on someone else’s likeness.
Quick Recap
Final checklist
- Use a compatible base model and model-specific script.
- Prepare varied, high-quality, consented face images.
- Use a rare token consistently.
- Start with DreamBooth LoRA unless you specifically need a full checkpoint.
- Record the Diffusers commit or release, model identifier, operating system, and GPU.
- Run the installed script’s
--helpoutput before training. - Use validation prompts and inspect intermediate checkpoints.
- Stop before the model memorizes recognizable training photographs.
- Load the output with the same model family and a compatible UI.
- Secure or delete personal images, checkpoints, and cloud storage when finished.

Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.