Crashes, No Sound, or Screen Glitches?
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.
Find the Right Drivers →Free scan · under a minute
ThatPainter is reader-supported. When you buy through links on our site, we may earn an affiliate commission. Learn More
WhisperFrame is a Raspberry Pi-based art installation that turns ambient conversation into a changing digital image. A four-microphone array captures speech in short segments, which are transcribed; GPT-4 reportedly extracts a visual topic, and Stable Diffusion generates artwork for a photo frame. The result is an AI-curated interpretation of the room’s conversation, not a literal or objective illustration of what people said.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minute#1 Best Overall

- 【PCM Recording and Automatic Noise Reduction】:This digital voice recorder is equipped with advanced dual noise reduction microphones and supports 1536 kbps PCM HD audio recording, ensuring crystal-clear sound capture in any environment. Recorder device with automatic noise reduction and voice-activated recording, the recorder only picks up the sound when there’s speech, reducing background noise,Excellent sound quality can meet the needs of students, journalists, music lovers and more people
- 【136GB Memory and Long Battery Life】Voice Recorder with Playback with 8GB built-in storage and includes a complimentary 128GB TF card, this digital voice recorder can hold up to 9775 hours of recordings in MP3 format or WAV format;Recorder for lectures with a built-in 1100mAh rechargeable lithium battery, this voice recorder can continuously record for up to 68 hours on a single charge, making it perfect for back-to-back meetings, interviews, or extended classroom sessions
- 【One Click Record and Save】: Our voice recorder supports one click recording and saving functions. Even when the product is in a powered-off state, simply push up the side recording button to immediately enter recording mode, and push down the recording button to save the recording. This allows for capturing as much information as possible.Easily transfer your recordings to your computer using the USB-C connection, allowing for fast and secure file management
- 【Easy-to-Use】This portable voice recorder is designed with a simple, user-friendly interface featuring a large, easy-to-read LCD screen. The voice-activated recording (VOR) feature makes hands-free operation a breeze. With one-touch recording, users can start or stop recording instantly, even during busy moments. A-B repeat function and password protection ensure that important segments are easily accessible and secure
- 【Portable and Durable Design】Designed with portability in mind, this lightweight screen recorder fits comfortably in your pocket or bag, weighing only 97 grams. Its sleek and durable metal casing ensures longevity and protection from everyday wear and tear. Whether you’re traveling, in the office, or attending a lecture, this compact recorder is always ready to capture clear, high-quality audio
First reported by Hackaday on September 22, 2023, WhisperFrame is best understood as a creative proof of concept—not a documented commercial product or a complete, currently verified build kit. Its architecture is compelling, but privacy implications and unreported technical details matter just as much as its visual novelty.
How WhisperFrame turns speech into images
According to Hackaday’s report, the reported pipeline is:
- A ReSpeaker four-microphone array captures room conversation.
- A Raspberry Pi records audio in segments of approximately 15–20 seconds.
- OpenWhisper transcribes the segments.
- Segments accumulate until roughly five minutes of audio has been collected.
- GPT-4 extracts a topic or image prompt from the transcript.
- Stable Diffusion generates an image from that prompt.
- The image is displayed on a digital photo frame.
The frame does not simply hear one sentence and immediately draw it. The report describes collecting repeated audio segments before sending the resulting transcript to GPT-4 to extract an image prompt from a single topic. A separate Adafruit MagTag can show the prompt or gallery information; Adafruit.io is reportedly used as an MQTT broker for that auxiliary display.
The hardware: a frame, a microphone array and a Raspberry Pi
The reported hardware includes:
- a Raspberry Pi computer;
- a ReSpeaker four-microphone array;
- a digital display or photo-frame assembly;
- an Adafruit MagTag for supplemental information;
- network connectivity and power.
The available coverage does not establish the Raspberry Pi model or RAM configuration, exact ReSpeaker revision, display size or resolution, storage medium, or enclosure design. It also does not say whether the main display is color, e-paper, or another type. Those details should not be filled in by assumption.
Likewise, the report does not establish whether Stable Diffusion runs on the Raspberry Pi, another local computer, or a remote service. The Raspberry Pi is part of the capture-and-orchestration concept, but “Raspberry Pi-powered” does not by itself mean every stage runs locally.
Why voice activity detection became necessary
The prototype reportedly had trouble when silence or ambient noise caused transcription to continue even though nobody was speaking. Voice activity detection was added to estimate whether speech was present and reduce unwanted capture during those periods.
Rank #2

- YOUR AI PERSONAL ASSISTANT FOR EVERYDAY PRODUCTIVITY: More than a voice recorder, Pocket works as your AI personal assistant to capture, transcribe, and summarize meetings, calls, and ideas instantly. Core features are included out of the box, with optional advanced tools available for power users.
- ONE-TAP RECORDING FOR REAL-LIFE MOMENTS: Capture meetings, phone calls, and in-person conversations instantly with a simple tap, no typing, no interruptions, just effortless note-taking anywhere you go.
- SMART AI INSIGHTS & ORGANIZATION: Pocket automatically turns recordings into clear summaries, key action items and structured conversation maps so you can quickly review what matters without digging through audio.
- TURN CONVERSATIONS INTO ACTION WITH “ASK POCKET”: Don’t just record, understand. Instantly ask questions across your meetings, extract key insights and generate next steps in seconds. All grounded in your recordings, so answers stay accurate and reliable.
- MAGSAFE COMPATIBLE FOR SEAMLESS USE: Easily attach Pocket to your iPhone or other MagSafe compatible devices for convenient, hands-free recording on the go. Perfect for capturing meetings, calls, and ideas without needing to hold your device.
This is a practical problem for any ambient audio installation. A microphone array can hear ventilation, fans, keyboards, dishes, traffic, television audio, and reverberation. Fixed recording windows can include unrelated sounds. Voice activity detection may reduce unnecessary processing, but it does not identify speakers, guarantee accurate transcription, or ensure that only intended speech is captured.
What the system actually understands
WhisperFrame does not understand a conversation in the human sense. Each stage introduces another interpretation:
- Microphones convert room sound into audio data.
- Speech recognition converts some of that audio into text.
- A language model selects or summarizes a topic from the transcript.
- An image model converts that textual prompt into a visual composition.
That chain can produce a striking image while still being semantically wrong, incomplete, or unrelated to what participants considered important. GPT-4 may choose an unusual phrase instead of the central subject, interpret sarcasm literally, flatten disagreement, favor a dominant speaker, or omit a minority viewpoint. The picture is an AI-mediated interpretation of a conversation—not an objective record of it.
From ordinary talk to strange artwork
The project’s appeal lies partly in its unpredictability. A conversation about an ordinary object might become a stylized still life. Fragmented or abstract discussion might become a surreal scene. Different groups in the same room could produce noticeably different results.
Hackaday describes the generated images as ranging from strange to impressive and warns that the associated gallery may contain NSFW material. Conversation can involve sexual subjects, violence, medical information, names, children’s speech, or workplace-confidential material, and resulting images may expose or transform those topics unexpectedly.
A responsible installation would need moderation and a way to reject, hide, or regenerate unsafe output. The source does not establish that WhisperFrame itself provides those controls.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Rank #3

- ENHANCED CONTEXT WITH MULTIMODAL INPUT: Capture audio, type notes, add images, and press to highlight key moments for richer context. During recording, instantly mark key moments with a single button press. Simultaneously enrich your audio by snapping photos of important documents or typing in ideas
- CHAT WITH YOUR RECORDINGS USING "ASK Plaud": Unlock deeper insights with this interactive AI. Ask questions, extract key points, draft emails, and get next-step suggestions—all grounded in your original audio for reliable, ready-to-use answers
- INTELLIGENT RECORDING WITH AI DIRECTIONAL AUDIO: Enjoy seamless, intelligent recording with Plaud Note Pro. Its AI automatically switches between call and meeting modes while recording, while directional audio and real-time spatial awareness minimize noise to capture voices with crystal clarity
- Everything Included: Includes Plaud Note Pro, magnetic case, magnetic ring, charging cable, and a free Starter Plan with 300 transcription minutes per month. Upgrade anytime in the Plaud app to Pro Plan (1,200 min/mo) or Unlimited Plan(Up to 24 hours of transcription per user per day)
- PREMIUM ULTRA-SLIM DESIGN WITH INSTANTVIEW DISPLAY: Meticulously designed, the AI Note Taker is just 0.12 inches thin and 1.06 oz —about the size of a credit card. Its sleek aluminum body with a textured wave finish features a vivid AMOLED display, letting you check battery and recording status at a glance, while it seamlessly works with Apple Find My to ensure you never misplace it
Privacy is the central trade-off
The artistic premise depends on listening to people who may not think of themselves as participants in an AI system. The reported design records repeated audio segments from conversations in the room, raising questions the original coverage does not answer:
- Are everyone present aware that speech is being captured?
- Is audio sent to external transcription or image services?
- Are raw recordings or transcripts retained?
- Can generated images be viewed outside the room?
- Is there a physical mute, pause, or recording indicator?
- Can the system work entirely offline?
- Can someone request deletion of an image or transcript?
The available report does not document encryption, retention, deletion, anonymization, consent notices, or a hardware mute switch. It also does not establish whether audio is continuously active or stored permanently. The safe description is that WhisperFrame is designed around ambient conversation capture and presents a meaningful privacy risk unless its operator supplies explicit consent and clear controls.
Recording laws differ by jurisdiction, so the project should not be labeled lawful or unlawful in general. Anyone deploying a similar installation should obtain local legal advice where necessary and use a clear notice, affirmative consent, visible recording status, and private-by-default data handling.
Is WhisperFrame reproducible in 2026?
The concept is reproducible in the broad architectural sense, but the 2023 article is not a complete build tutorial. It names major components without providing a verified bill of materials, installation process, or maintained software package.
Recommended Free Tools
| Area | What the report establishes | What still needs verification |
|---|---|---|
| Computer | Raspberry Pi | Model, memory, operating system, and current compatibility |
| Microphone | ReSpeaker four-mic array | Exact revision, drivers, and placement |
| Speech recognition | OpenWhisper API | Current availability, endpoint, pricing, and authentication |
| Language model | GPT-4 extracts an image prompt | Exact model, prompt design, and current API behavior |
| Image generation | Stable Diffusion | Version, hosting arrangement, hardware, and moderation |
| Messaging | Adafruit.io MQTT broker | Topics, account setup, and current plan limits |
| Display | Digital frame plus MagTag information display | Display model, resolution, firmware, and enclosure |
The named services and models should be treated as historical references. Their names, APIs, pricing, availability, and compatibility may have changed since September 2023. A builder starting now would need to verify every dependency rather than assume the original stack remains plug-and-play.
Where the system can fail
WhisperFrame combines several failure-prone stages:
Rank #4
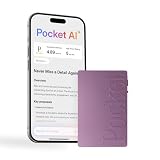
- YOUR AI PERSONAL ASSISTANT FOR EVERYDAY PRODUCTIVITY: More than a voice recorder, Pocket works as your AI personal assistant to capture, transcribe, and summarize meetings, calls, and ideas instantly. Core features are included out of the box, with optional advanced tools available for power users.
- ONE-TAP RECORDING FOR REAL-LIFE MOMENTS: Capture meetings, phone calls, and in-person conversations instantly with a simple tap, no typing, no interruptions, just effortless note-taking anywhere you go.
- SMART AI INSIGHTS & ORGANIZATION: Pocket automatically turns recordings into clear summaries, key action items and structured conversation maps so you can quickly review what matters without digging through audio.
- TURN CONVERSATIONS INTO ACTION WITH “ASK POCKET”: Don’t just record, understand. Instantly ask questions across your meetings, extract key insights and generate next steps in seconds. All grounded in your recordings, so answers stay accurate and reliable.
- MAGSAFE COMPATIBLE FOR SEAMLESS USE: Easily attach Pocket to your iPhone or other MagSafe compatible devices for convenient, hands-free recording on the go. Perfect for capturing meetings, calls, and ideas without needing to hold your device.
- Capture: Quiet speakers, distant microphones, room reverberation, and overlapping speech can degrade the recording.
- Transcription: Accents, dialects, music, and background noise can produce incorrect or fabricated text.
- Topic selection: The language model may emphasize novelty over importance or misread humor and sarcasm.
- Image generation: The result can be biased, inappropriate, or visually disconnected from the discussion.
- Networking: Lost connectivity, invalid credentials, rate limits, and service outages can interrupt the pipeline.
- Service changes: API formats, model availability, and moderation rules can change.
- Cost: Repeated transcription, language-model, and image-generation requests may create usage charges.
The five-minute collection period alone means the system is not necessarily immediate. Uploading, transcription, prompt generation, image generation, downloading, and display refresh add further delay. The original article does not provide an end-to-end latency measurement, so no reliable response time should be inferred.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.What a safer version would add
A production-quality ambient art frame would benefit from:
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →- explicit consent from everyone whose voice may be captured;
- a visible recording indicator;
- a physical mute or pause control;
- short, documented retention limits for audio and transcripts;
- private-by-default image storage and display;
- output moderation and a reject/regenerate workflow;
- clear handling for API failures and sensitive topics;
- an offline mode, where practical;
- push-to-talk or event-triggered capture instead of room-wide monitoring.
Alternative designs can preserve part of the idea with fewer risks. Offline speech recognition reduces cloud exposure but may require more capable hardware. Local language and image models avoid some external requests and per-call fees while increasing setup and maintenance demands. Manual prompt entry removes transcription and consent problems but also removes the distinctive ambient interaction. A non-generative visualization—such as color, typography, or geometric forms derived from text—could express conversational change without displaying a photorealistic interpretation.
Who is WhisperFrame for?
The project is a natural fit for Raspberry Pi builders, interactive-art creators, creative technologists, AI-art experimenters, and museum or gallery teams exploring ambient interfaces. It is less suitable for a privacy-sensitive home, an office without an explicit consent policy, a family seeking predictable child-safe output, or anyone looking for a supported plug-and-play product.
Readers interested in assembling a similar system can begin with official hardware references for Raspberry Pi, Seeed Studio’s ReSpeaker range, Adafruit hardware, and Adafruit IO. These links identify relevant product and service categories; they do not confirm the exact parts used by WhisperFrame or guarantee compatibility with its 2023 implementation.
The larger idea
WhisperFrame makes conversation visible by inserting several layers of computation between speech and image. That is what makes it interesting as art: the frame is not a mirror, but an interpreter. It captures fragments, assembles context, chooses what seems visually salient, and turns that choice into a synthetic picture.
Best Value
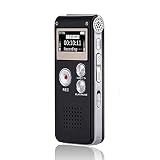
- 【Simple Operation】- switch on your voice recorder, one button for recording. press the "REC", start the recording, press "STOP", end the recording, press “PLAY”, listen what you just recorded, and then Press A-B, select your important section to repeat. Easy to playback with inner powerful speaker, support external sound speaker playback, let you enjoy superior recording quality.
- 【Clear Voice Record】- high quality recording with noise redution, you will get super clear recorded voice, the sensitive microphone help you to catch speaker's words in an interview, lectures, meetings.
- 【Voice Activated Recording】- automatic voice reduction function, it starts recording when sound is detected or turn to standby state, saving recording time and reduce power consumption.
- 【 Player Function】- this voice recorder can be used as an music player, you could enjoy the music after your tired study, meeting and so on. Also can function as a detachable data storage device.you can take along your favorite pictures and documents whenever you go.Simply cut-and-paste or drag-and -drop files to or from it via USB connection, the player will appear as a removeable drive in Windows.
- 【High quality and long time】 uses DSP noise reduction technology to filter out environmental noise, has high-quality recording, 【1536kbps】to restore the real scene. It can continuously record for more than 30 hours and play for 7 hours.
It is also what makes the project difficult to treat as an ordinary smart display. The installation depends on ambient audio capture, services whose processing arrangements are not fully documented, uncertain operating costs, model bias, unpredictable imagery, and engineering details that the original article leaves unspecified.
As a demonstration, WhisperFrame is a vivid example of ambient computing becoming visual material. As a deployable system, it needs much more documentation—especially around consent, retention, moderation, failure recovery, and current software compatibility—before it can be considered a reliable installation.
FAQ
Is WhisperFrame a product you can buy?
The available coverage describes WhisperFrame as a maker project or art installation, not a finished commercial product. It does not establish availability for purchase or a supported build kit.
Does WhisperFrame draw an image from each sentence?
No. The 2023 report says it collects 15–20-second audio segments until roughly five minutes of audio has accumulated, then uses a transcript to extract a topic or prompt for image generation.
Free tools Windows power users keep installed
One-click scans. No signup required.
Does WhisperFrame process everything locally?
The report does not establish where image generation runs or fully document the processing arrangement. Do not assume that Raspberry Pi involvement means all audio, language, and image processing happens locally.
Can the generated image accurately represent a conversation?
Not reliably. Speech recognition, topic selection, and image generation can each distort or omit meaning, so the result is an AI interpretation rather than an objective record.
What does a builder still need to verify?
A builder would need to verify the exact hardware, software dependencies, API availability and costs, processing location, moderation, privacy controls, and current compatibility. The Hackaday article does not provide a complete maintained build guide.
Quick Recap

Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Scan for outdated or missing drivers - takes under a minute3Repair Windows errors before they cause bigger problems